Join the conversations to shape a safer, more efficient, and sustainable industrial future!
Recently active
OpenID Connect is now available on Open Industrial Data (OID). When you sign up to Cognite Hub, you get an account and can access both the publicdatacdm and publicdata projects.Whether you are new to OID or have been using API keys to access the data in this project, here’s all you need to get started with OIDC. Connection DetailsThe credentials for each project are listed below. Please use the details corresponding to the project you wish to access. For the publicdatacdm Project Details for Postman and Python SDK: Tenant ID: 48d5043c-cf70-4c49-881c-c638f5796997 Client ID: 1b90ede3-271e-401b-81a0-a4d52bea3273 project: publicdatacdm CDF_CLUSTER: api App name: OID-Api Note: This app registration is configured with replyURLs for Postman and to run Python SDK apps locally with http/https.Details for JavaScript Applications: Tenant ID: 48d5043c-cf70-4c49-881c-c638f5796997 Client ID: dea6bb8d-0f48-4bf0-a469-176fc19edc14 project: publicdatacdm CDF_CLUSTER: api App name: OID-js
Hi, Stig, your guide to Open Industrial Data (OID) here 👋In this article, I will introduce you to the reference data set of a industrial process system that the Open Industrial Data project contains. Analogous to what the Iris, Titanic, and gap-minder data sets are to learning data science tools, the OID project will be your entry ticket to working with industrial data. Here is a short technical description of the system on Valhall that is shared on the Open Industrial Data project. System descriptionThe data set represents the first of four stages of treatment of natural gas on the Valhall PH (Production Hotel) platform. The purpose of the gas train is to dry and compress the gas to meet the required export pressure and specification, with a total capacity of 4,06 [MSm3/d] (143 [MMscf/d]).The first stage compressor (23-KA-9101) is an electrically-driven, fixed-speed centrifugal compressor that receives gas from the separators at approximately 3 [barg] pressure. Before reaching the co
ProblemSmart Factory is a Flows custom app that runs inside the CDF iframe with hideShell=true. In that mode users cannot open the Fusion account menu to sign out.HostAppAPI from connectToHostApp (@cognite/app-sdk) already exposes getAccessToken(), getProject(), getBaseUrl(), navigateExternal, and setHideShell (see Flows Auth API). It does not provide a way to end the Cognite Auth / Fusion session from the app:There is no logout() (or similar) on HostAppAPI. Cognite Auth RP-initiated logout (end_session_endpoint at https://auth.cognite.com/oauth2/sessions/logout) expects an id_token_hint. The host only exposes a CDF access token via getAccessToken(), not an ID token. Fusion’s own logout uses that end-session endpoint with id_token_hint and post_logout_redirect_uri. From the iframe we cannot obtain a valid id_token_hint.We also cannot use setHideShell(false) just to expose Cognite’s logout UI. Proposed solutionExtend HostAppAPI with one of:logout(options?) – the host clears the Cognite
SummaryLet Atlas create a Chart calculation from a natural-language request and plot the result as a time series chart.Today a user can build that calculation by hand in the Charts node editor (sources, constants, functions, and an output node), or ask Atlas to analyze stored time series. Atlas can embed a bar chart, KPI, table, or an existing Charts time series in a reply. It cannot turn a formula, for example a pressure difference, a unit conversion, or a scaled flow, into a calculation and show that calculated series on a line chart unless the result already exists as a time series in CDF. ProblemEngineers and operators compare derived signals as often as raw tags: pressure drop, API gravity, unit conversion, ratio of two flows, a moving average. Those series are usually not stored in CDF.The path today is manual: Find the source time series. Open Flows > Charts, create a chart, and add the series. Open Add data > Create calculation and wire sources, constants, and functio
The ability to define a CogniteUnit on a column in a container is very powerful. However, there are many situations where we are not able to define one common unit for an entire column.One example is LCI/Equipment data. Properties like length, volume, weight will have different units for a massive compressor vs a tiny bolt. We want to avoid doing unit conversion on ingestion since it introduces added complexity and risk (how to handle that a unit is not specified in the source), and it will also require the end user to do the unit conversion to get the number on the unit from the source system. One possible approach could be to have a column with the CogniteUnit instanceid, and then instead of defining the fixed CogniteUnit for a column we define the column with the unit.
One of the more important properties for industrial data is the Engineering units of a value (unit of measure).Today we can add a CogniteUnit, both to a timeseries and to a column in a data model container, which will enable unit conversion on consumption.When we ingest the data from our source systems, we need to identify the unit as it is described in the source system, and then match it to the correct CogniteUnit. Many of our source systems do unfortunately not follow a standard for engineering units (leading to the need for the looooong alias list in the unit catalogue).But some of our systems specify the unit via a standard. For AkerBP it is mainly CFIHOS and OPC-UA (which really is UN/CEFACT unit codes)It would be very helpful to both being able to identify a unit via these standards when the unit is populated, but also when it is consumed.Eg: Temperature in Celsius isCFIHOS-60001435 CE/CEFACT/OPCUA unitID=4408652I can add the CFIHOS code to the alias list (we are doing this now)
How should data write-back be implemented in an application developed using Cognite Flows? Specifically, where should application-generated files and structured data be persisted, which CDF services should be used for different data types, and how should the write-back layer integrate with the broader CDF architecture?
Hi Cognite Community,We are looking at ingesting approximately 1 million engineering and operational documents into CDF, including equipment manuals, datasheets, inspection reports, SIL/HAZOP studies, operating procedures, technical studies, maintenance reports, and other asset-related documents.Our key requirement is for an Atlas AI agent to answer questions across this entire document repository without the user having to identify or pinpoint a specific document first.For example, a user should be able to ask:“What are the recurring compressor seal issues reported across our engineering and operational documents?”The user may not know which documents contain the relevant information. We therefore expect Atlas AI to discover the appropriate documents/passages, retrieve the relevant content, and generate a grounded response with references to the source documents.According to Cognite's documentation, CDF Semantic Search does create vector embeddings for PDF documents as part of the bui
Several Data model views contain large volumes of historical data, which can impact performance, scalability, and overall user experience. A potential improvement would be to implement a historical data archiving strategy by separating older records from active datasets.For example, records beyond a defined retention period could be moved to dedicated archive views, while primary views retain only the most recent and frequently accessed data. Another option would be to maintain a separate historical reporting layer specifically designed for long-term analysis and archival reporting.This approach would help improve query performance, reduce dataset sizes, and enhance usability for analytics and reporting tools. Users would benefit from faster data retrieval, shorter dashboard load times, and a more responsive self-service analytics experience, while also reducing processing overhead on the platform.
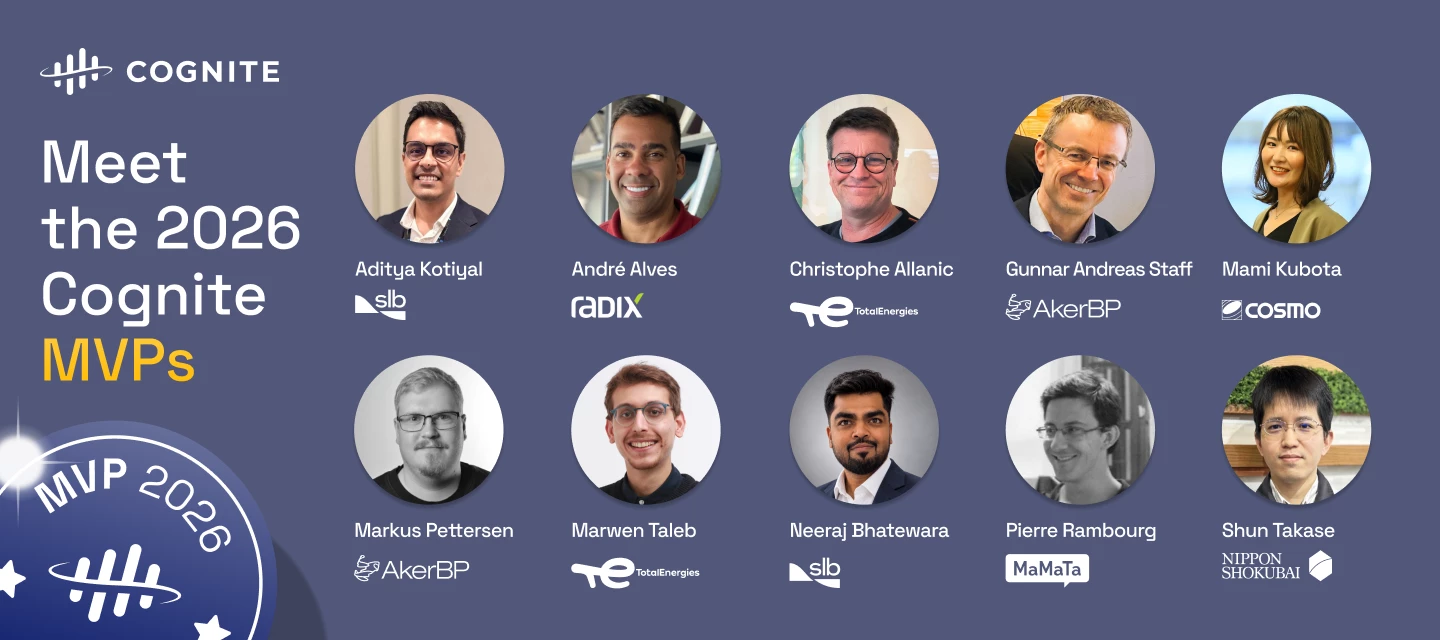
Today we’re proud to announce the 2026 Class of Cognite MVPs: ten community members who have gone above and beyond in the Cognite Hub this past year.MVPs are the people who make this community what it is. They answer questions, share what they’ve learned from real projects, give honest feedback that helps shape our products, and welcome newcomers. Their expertise and generosity have helped many members get unstuck and get more value out of Cognite Data Fusion.Please join us in congratulating:Aditya Kotiyal, SLB André Alves, Radix Christophe Allanic, TotalEnergies Gunnar Andreas Staff, Aker BP Mami Kubota, Cosmo Oil Markus Pettersen, Aker BP Marwen Taleb, TotalEnergies Neerajkumar Bhatewara, SLB Pierre Rambourg, MaMaTa Shun Takase, Nippon ShokubaiTo everyone on this list: thank you! Your contributions make this community a better place for everyone, and we’re lucky to have you.Want to be part of next year’s class?MVPs are recognized for helpful answers, knowledge sharing, and the posit
Whether CDF natively supports semantic/ontology-based relationship modelling (named, typed relationships like contains, hasTimeSeries, performedOn with direction/cardinality/metadata), and whether Atlas AI and other consumers can traverse that semantic meaning rather than just node-to-node links.
In order to delete nodes in CDF in a given View because of deletes in the Fabric source table, we need to extract necessary fields for all rows in Fabric to construct the space and ExternalId, and then compare this with a full extraction of the space and externalId in the View.In one example with ~400k rows/nodes, it takes 1-2 minutes to get the data from Fabric. However, the cdf_nodes is several orders of magnutide slower.Only extracting space and externalId for 400k nodes in the View takes ~25 minutes Adding a Where clause to check if the externalId has a given prefix as a safeguard makes the query time out.Using cdf_data_models or other functions does not seem to help either. Is there a reason that listing ids for nodes is so slow? And are there other ways to go about this use case?
Hello, Is timeSeriesAcl:read acl required for data point subscription consumption? Although the client has timeSeriesSubscriptionsAcl:read. We recieve: CogniteAPIError: Missing capability to read Time series | code: 403. When calling: ‘client.time_series.subscriptions.iterate_data’.Thanks
Hi, Is it possible to perhaps add a "warning" status to Extraction Pipelines? Sometimes it is nice to not just flag something as a failure but still something that should be flagged/raised.
I feel that when zooming in with the mouse wheel, the increment at which it zooms is too small. For instance, when I zoom into a canvas with 5 drawings it takes 15 mouse wheel up’s to get to the zoom level that I am able to read any one of those drawings. Then when zooming back out it takes 15 to see the whole canvas again.
Hello Community, I am just trying to understand the zero copy connection to databricks. I understand from the examples at cognite-databricks/README.md at main · cognitedata/cognite-databricks · GitHub, that CDF exposed its data through the Unity Catalog, help register its views (including Core CDM etc) and query them from databricks notebook. How about the reverse - for example to access data from databricks from outside databricks, does “zero copy” applies. For example, I see one can query the SQL warehouse using service principals and PATs. Is there a zero copy way, that I am missing? ThanksAlex
RequestProvide the ability to change bounding box colors based on the status or metadata of the associated document, inspection data, or record.The goal is to make important status information visible directly within the working view, allowing users to recognize items that may require attention without opening each item individually.Problem / opportunityWhen reviewing documents or records together, users need a clear way to distinguish their status. For example, they may need to know whether a document is managed, whether it represents the latest revision, or whether an associated inspection is overdue.Status-based bounding box indicators would bring that context into the visual review, rather than requiring a separate status check for every item.Use Case Examples1. Managed versus unmanaged documentsUse different bounding box colors to distinguish documents identified as managed from those identified as unmanaged.Example: A user reviewing several documents could immediately identify wh
Its a need to have the schedules tab available for all users using InField. As a technician it is beneficial to see all upcoming check lists in a schedule view just as the lead technician is able to today. This gives a much better overview of all lists coming up in the next week.The only downside is that the technicians don’t need to set a check list to “Ready” status. Its proposed to give technicians a display version of schedules, without the possibility of setting lists to “Ready”.
Today there is no way to customize the way instances are ordered within hierarchy views. It would be beneficial with a method that could allow instances to be ordered to reflect the physical build of the monitoring system. Granted the information order can be delivered from the source into CDF, we can re-use the information to create a hierarchy view that more closely represents reality and what users may already be familiar with. However, in our case, we may have a sub-hierarchy (e.g. S1 data for Yggdrasil - Yggdrasil being the root of the hierarchy) that has one way of defining the order, while a different sub-hierarchy (e.g. SAS data for Yggdrasil) may not have exposed this information.
Hi Cognite team,>> On project `essc-sandbox-44` (cluster `westeurope-1`), we've configured a published AI Agent's data tools with **"Follow access scope defined manually"** set to a single instance space (`beveragemanufacturer`), but the tools scan the entire project's cross-space instance population instead of the scoped space. We verified via the SDK that the agent's "Found data of type" counts match the global totals exactly (e.g., 31,120 Process Alarms and 39,260 Downtime Events project-wide) while the scoped space holds only ~334 instances total — producing 6+ minute responses. It reproduces across three different tool types and is unaffected by reducing the data model, removing tools, or adding explicit prompt-level scoping.>> The attached document has full environment details, the verified evidence, reproduction steps, and our specific questions. Our main question: is this scope setting meant to filter DMS retrieval by space, and if so, is the cross-space scan a know
Hello everyone,I am a UI/UX Designer who is new to Cognite Data Fusion and the Cognite ecosystem.I would like to better understand:How UX designers typically contribute to CDF projects Common user journeys and workflows within CDF Design challenges users face when working with industrial data Available design guidelines, design systems, or UI best practices for Cognite applications Recommended learning resources for someone coming from a traditional enterprise UX backgroundAny examples, documentation, or advice would be greatly appreciated.Thank you!
BackgroundWe want to build a new dashboard for our operations department in CDF Adaptive Experience. Our plan is to show existing time series, custom apps, and dashboards together as widgets in one place.While setting this up, we found the gaps below. We'd like to request the following features.1. Direct integration with CanvasCurrent: We can't create a direct link to a Canvas, and we can't embed a Canvas in the dashboard. Request: Allow Canvas content to be displayed on new dashboards in Adaptive Experience.2. Bulk import of edited charts or charts placed on a CanvasCurrent: Charts created on a Canvas (multiple charts) can't be embedded directly in the dashboard. The only options are to pull out each time series one by one, or to add a launcher through Flows. The launcher only opens a separate screen, which adds an extra step for users. Request: Let us paste edited charts into the dashboard. Ideally, a whole Canvas could be imported at once, with its charts registered automatically.3.
Hi Cognite Community,We have a requirement to extend the CDF 3D experience beyond displaying attributes from the Core Data Model, so that users can visualize related transactional and operational information as configurable layers directly on the 3D model.Our industrial knowledge graph connects equipment and functional locations to multiple types of information, for example:SAP Notifications and Work Orders Maintenance Plans Inspection findings Reliability events / Bad Actors RCA and TFN records MOC records Alarms and operational events Engineering and operational documents Time-series conditions and calculated KPIsThe Cognite Core Data Model provides standardized industrial concepts and can be extended through additional models and relationships. [docs.cognite.com], [docs.cognite.com]However, we would like the 3D visualization to make greater use of these contextual relationships, rather than limiting the user experience primarily to the attributes directly associated with the core 3D
Hi Cognite Community,We have a requirement for CDF Charts to dynamically use configured tag limit attributes as chart thresholds, rather than requiring users to manually enter static threshold values on an ad-hoc basis.For industrial tags/time series, we maintain multiple engineering and operational limits, for example:High / High-High limits Low / Low-Low limits Operating upper and lower limits Design limits Alarm limits Safe operating limits Other tag-specific engineering thresholdscurrently supports configuring thresholds for time-series analysis and monitoring. However, we would like these thresholds to be dynamically sourced from the contextualized attributes associated with the tag/time series, rather than manually entering a value each time a chart is created.Expected capabilityFor example, if a pressure tag has contextualized attributes such as:High: 80 bar High-High: 90 bar Low: 30 bar Low-Low: 20 bar Design Pressure: 100 barWhen the user adds that time series to a CDF Chart,
Hi Cognite Community,We have a requirement to provide configuration control over how data model objects are organized and presented in CDF Search and the Details view.As our industrial knowledge graph grows, an asset or equipment can be connected to many different object types, such as:Functional Location → Equipment → Time Series → Notifications → Work Orders → Maintenance Plans → Documents → Engineering Studies → MOCCDF already allows users to search and navigate connected resources. Data explorer - Cognite Docs However, for a large enterprise data model, the sequence in which these related objects are presented becomes important for usability and business context.We would like the ability for an administrator/data model owner to configure: Search pane object ordering Define which object types appear first and in what sequence. Details view tab ordering Configure the sequence of related-object tabs when a user opens an Asset, Equipment, Functional Location, or another object. Sho
Already have an account? Login
No account yet? Create an account
Enter your E-mail address. We'll send you an e-mail with instructions to reset your password.


 Check the
documentation
 Ask the
Community
 Take a look
at
Academy
 Cognite
Status
Page
 Contact
Cognite Support