Seasoned ⭐️⭐️
Apr 1, 2024 10:57 PM UTC
Solved

How to load sequences from a dataframe in batches?

Hi everyone,


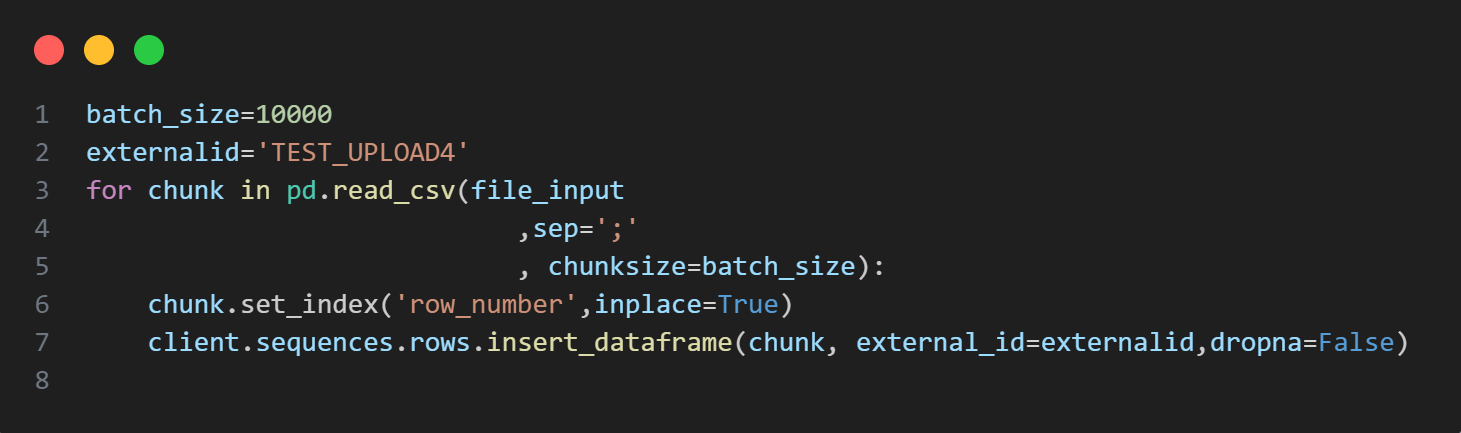
I'm loading sequences from a file that has 11 million rows, and I would like to load it in batches, where each batch is a dataframe. As I load by batch, the rows that the sequence already had are being deleted, leaving only the last batch. How can I load each batch without deleting the previous one?


This is the code I use to read the file in batches and load rows into the sequence. It is assumed that the sequence is already created.
 

Regards,

Karina Saylema
@Aditya Kotiyal  @HanishSharma  @Jason Dressel  @Jairo Salaya @Liliana Sierra 


Andrian Gasper
Practitioner ⭐️⭐️⭐️
Apr 2, 2024 1:35 PM UTC

Hi @Karina Saylema 

Your code seems correct.
Could you make sure that “row_number” is unique? 

If you try the code bellow, are you encountering the same issue?
 

batch_size = 10000
external_id = 'TEST_UPLOAD4'
start_row = 0 # Initialize a starting row number

for chunk in pd.read_csv(file_input, sep=';', chunksize=batch_size):
chunk.drop(columns=["row_number"], inplace=True)
chunk.index = range(start_row, start_row + len(chunk))
client.sequences.data.insert_dataframe(chunk, external_id=external_id, dropna=False)
start_row += batch_size


4 replies

Andrian Gasper
Practitioner ⭐️⭐️⭐️
Practitioner ⭐️⭐️⭐️
Apr 2, 2024 1:35 PM UTC

Hi @Karina Saylema 

Your code seems correct.
Could you make sure that “row_number” is unique? 

If you try the code bellow, are you encountering the same issue?
 

batch_size = 10000
external_id = 'TEST_UPLOAD4'
start_row = 0 # Initialize a starting row number

for chunk in pd.read_csv(file_input, sep=';', chunksize=batch_size):
chunk.drop(columns=["row_number"], inplace=True)
chunk.index = range(start_row, start_row + len(chunk))
client.sequences.data.insert_dataframe(chunk, external_id=external_id, dropna=False)
start_row += batch_size


Expert ⭐️⭐️⭐️⭐️
Apr 2, 2024 3:47 PM UTC

@Karina Saylema 

I think what’s happening is that chunk.set_index() is resetting the index for each chunk which is resulting in the sequence rows being overwritten because the row indexes are the same as the prior batch.
I’m not a pandas expert, but something like explicitly setting the index based on your batch size might be what you are looking for: https://pandas.pydata.org/docs/reference/api/pandas.RangeIndex.html

Hope this helps,
Jason

Seasoned ⭐️⭐️
Apr 3, 2024 5:13 PM UTC

Thanks @Andrian Gasper, @Jason Dressel for your help 

Andrian Gasper
Practitioner ⭐️⭐️⭐️
Practitioner ⭐️⭐️⭐️
Apr 4, 2024 11:59 AM UTC

@Karina Saylema You can mark this questions as answered, if you believe it is. :)